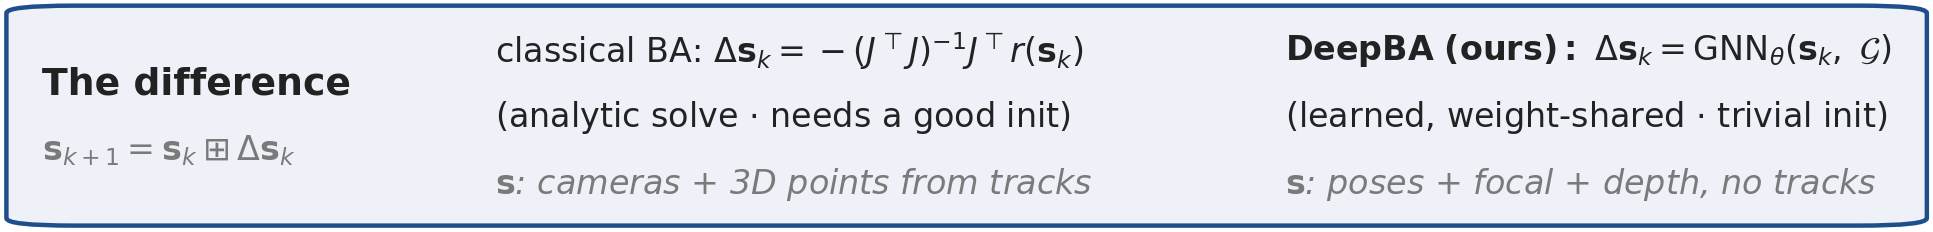
We present DeepBA (Deep Bundle Adjustment), a graph neural network (GNN) that recovers camera poses, intrinsics, and scene structure from 2D matches across an arbitrary number of views. Rather than solving a non-linear least-squares problem per scene, DeepBA amortizes bundle adjustment into a learned graph network that iteratively refines its estimate from geometric residuals. Where classical SfM computes its updates analytically and needs careful initialization, DeepBA learns them and converges from a cold start. It is trained with scale-invariant supervision (ground-truth rotation, translation direction, and intrinsics, plus reprojection self-consistency), so datasets with arbitrary metric units can be mixed without per-scene normalization. DeepBA is decoupled from the matcher. At 2.04M parameters, it outperforms prior learned SfM from matches on scene reconstruction and on most pose metrics, is competitive with classical SfM at moderate accuracy thresholds and overtakes it in wall time as the view count grows, and approaches monolithic image-to-geometry transformers such as VGGT (~1.2B parameters) with greater modularity.

Each iteration reads the current state and predicts the next update of poses, focal lengths and depth. The same small network runs for every iteration and every scene. With 2.04M parameters, it is about 590× smaller than VGGT (~1.2B).
Following the track-free idea of TFD-SfM, the state is one pose, one focal length and one depth map per image. Pairwise matches are enough, so no tracks have to be built, and any matcher can be plugged in.
Rotations, translation directions and intrinsics are supervised, plus reprojection self-consistency. Datasets with arbitrary metric units are mixed without per-scene normalization.
DeepBA on the eLoFTR matches of every scene, replayed in 3D: drag to orbit, scroll to zoom, and scrub the slider through the iterations. Each frame is centered and scaled to fit, since the scene grows from unit depth, and 20k of the matches are shown, lifted by DeepBA's depth. The numbers are the run's relative rotation and translation accuracy at 5° and its pose AUC at 30°, without a final bundle adjustment.
Multi-view pose accuracy: relative rotation and translation accuracy at 10° (RRA, RTA). The paper also reports 3° and 5°. Bold: best, underlined: second best within each group. Grey: image-to-geometry methods, for reference. †: ground-truth intrinsics and a final classical bundle adjustment. ‡: DeepBA's eLoFTR correspondences.
| Method | DTU | Mip-NeRF 360 | ETH3D | IMC2021 | ||||
|---|---|---|---|---|---|---|---|---|
| RRA | RTA | RRA | RTA | RRA | RTA | RRA | RTA | |
| Classical SfM | ||||||||
| COLMAP (SIFT) | 87.3 | 82.6 | 100.0 | 100.0 | 96.7 | 96.4 | 95.7 | 89.3 |
| GLOMAP (SIFT) | 87.2 | 78.6 | 100.0 | 100.0 | 96.6 | 91.5 | 96.0 | 88.2 |
| COLMAP (eLoFTR)‡ | 100.0 | 99.5 | 100.0 | 100.0 | 76.9 | 75.5 | 97.2 | 91.5 |
| GLOMAP (eLoFTR)‡ | 97.9 | 96.8 | 100.0 | 100.0 | 61.6 | 56.9 | 97.8 | 91.2 |
| Learned image-to-geometry | ||||||||
| MASt3R-SfM | 100.0 | 99.5 | 86.9 | 84.0 | 79.0 | 74.6 | 97.5 | 87.7 |
| VGGT | 100.0 | 100.0 | 100.0 | 98.5 | 96.9 | 79.6 | 100.0 | 91.9 |
| Learning-based SfM from matches | ||||||||
| RESfM (SIFT)† | 22.0 | 26.0 | 12.0 | 12.1 | 4.5 | 3.8 | 84.6 | 81.2 |
| GASfM (SIFT)† | 40.8 | 44.1 | 41.1 | 44.3 | 12.1 | 10.7 | 86.3 | 75.3 |
| RESfM (eLoFTR)†, ‡ | 36.8 | 39.3 | 11.3 | 12.0 | 19.6 | 19.4 | 84.8 | 79.8 |
| GASfM (eLoFTR)†, ‡ | 38.8 | 42.4 | 54.7 | 57.6 | 27.2 | 29.4 | 92.2 | 90.8 |
| DeepBA | 100.0 | 99.6 | 73.5 | 86.5 | 69.1 | 49.1 | 99.0 | 87.3 |
Camera pose on CO3Dv2 and RealEstate10K, 10 frames per scene. Time: seconds per scene on one H100, as matching + solver for the methods that take matches.
| Method | CO3Dv2 | RealEstate10K | Params | Time | ||
|---|---|---|---|---|---|---|
| RRA@15 | RTA@15 | AUC@30 | AUC@30 | |||
| Classical SfM | ||||||
| COLMAP (SIFT) | 86.3 | 79.9 | 74.9 | 46.5 | – | ~2+3 s |
| GLOMAP (SIFT) | 86.6 | 76.2 | 71.1 | 71.7 | – | ~2+2 s |
| COLMAP (eLoFTR)‡ | 89.7 | 83.5 | 77.0 | 80.9 | – | ~7+11 s |
| GLOMAP (eLoFTR)‡ | 82.1 | 72.3 | 67.6 | 72.7 | – | ~7+5 s |
| Learned image-to-geometry | ||||||
| PoseDiffusion | 87.7 | 80.0 | 71.6 | 39.6 | 39.0M | ~115 s |
| DUSt3R | 98.3 | 82.1 | 72.9 | 79.9 | 577.8M | ~7 s |
| MASt3R | 99.2 | 92.1 | 84.7 | 91.1 | 695.3M | ~9 s |
| VGGSfM | 94.3 | 85.8 | 80.5 | 89.5 | 281.2M | ~10 s |
| VGGT | 99.3 | 92.1 | 85.1 | 85.3 | ~1.2B | ~0.2 s |
| Learning-based SfM from matches | ||||||
| RESfM (SIFT)† | 62.7 | 55.5 | 51.1 | 48.9 | 0.7M | ~2+13 s |
| GASfM (SIFT)† | 79.1 | 73.9 | 68.6 | 75.4 | 145.2M | ~2+0.5 s |
| RESfM (eLoFTR)†, ‡ | 61.1 | 54.0 | 48.2 | 63.7 | 0.7M | ~7+13 s |
| GASfM (eLoFTR)†, ‡ | 79.9 | 77.3 | 71.2 | 82.8 | 145.2M | ~7+2 s |
| DeepBA | 97.4 | 89.2 | 78.6 | 84.0 | 2.04M | ~7+3 s |

scan82, Mip-NeRF 360 bicycle, ETH3D
delivery_area and IMC2021 london_bridge (a 25-view bag). The number after each
dataset is that scene's image count. 3D points, estimated cameras in
green and ground-truth cameras in grey.

bonsai, with every method
using the same eLoFTR matches on one H100 (matching time dashed). Right: time per iteration against the number of matches.

room.
DeepBA localizes a new image with the same refinement step it uses for reconstruction. The map stays frozen, and only the query camera and its depth are refined, so DeepBA needs neither PnP nor the query's intrinsics.
One held-out image registered against the frozen 25-image DeepBA map (blue cameras and points). The query camera (green) starts at the mean pose of the map cameras (their chordal-mean rotation and mean centre), the same start for every query, with no PnP estimate. DeepBA's update moves it, together with its lifted 3D points, onto the map. After 10 iterations the rotation error is 3.5° (frame 10, from 109°) and 4.0° (frame 42, from 19.1°). Grey: the ground-truth camera.
Four localizers register the same held-out queries against the same frozen DeepBA map, so only the registration step differs.
A 25-image DeepBA map, frozen, and 100 query frames registered one by one. Query-camera trajectories against the ground truth (grey): DeepBA (green), PnP+RANSAC (orange) and HLoc (cyan), both given the ground-truth query intrinsics, and the focal-solving PnPf+RANSAC (pink). The table gives the final median camera-centre error (ground-truth units, metres on ScanNet; HLoc localizes the 75 queries outside the map) and the map's own error (ATE) for all eight scenes we ran. The first two clips are the scenes of the paper. The other four are the two best DeepBA maps per dataset (lowest map ATE) besides those. Bold: best, underline: second best per scene (among the four localizers).
| Scene | Map ATE | PnP+RANSAC + GT K | PnPf+RANSAC | HLoc + GT K | DeepBA |
|---|---|---|---|---|---|
CO3Dv2 hydrant | 0.216 | 0.342 | 0.254 | 0.582 | 0.185 |
CO3Dv2 toytruck | 0.126 | 0.127 | 0.184 | 0.222 | 0.167 |
CO3Dv2 motorcycle | 0.204 | 0.254 | 0.264 | 0.373 | 0.240 |
CO3Dv2 teddybear* | 7.969 | 7.509 | 7.619 | 7.674 | 7.628 |
ScanNet scene0042_00 | 0.064 | 0.055 | 0.066 | 0.075 | 0.059 |
ScanNet scene0000_00 | 0.046 | 0.047 | 0.090 | 0.058 | 0.053 |
ScanNet scene0050_00 | 0.201 | 0.174 | 0.208 | 0.189 | 0.199 |
ScanNet scene0011_00 | 0.086 | 0.057 | 0.083 | 0.085 | 0.061 |
*DeepBA's 25-image teddybear map fails (half of the orbit is flipped, map ATE 7.97),
so every localizer registered against it fails too.
Camera localization on 7-Scenes: median translation and rotation error (cm/°) under the protocol of HLoc. The first row is HLoc as published, with its own map from the full ~4,000-image TrainSplit. The other four register the same queries against the same frozen DeepBA map, built from 200 TrainSplit images. Bold/underlined: best/second best among these four, per column. The ground-truth rotations are projected onto SO(3) before scoring, since they are not exactly orthonormal.
| Method | Intrinsics needed | Chess | Fire | Heads | Office | Pumpkin | Kitchen | Stairs |
|---|---|---|---|---|---|---|---|---|
| HLoc, ~4,000-image map | yes | 2/0.79 | 2/0.87 | 2/0.92 | 3/0.91 | 5/1.12 | 4/1.25 | 6/1.62 |
| Same map, same queries: only the registration step differs | ||||||||
| HLoc, DeepBA map | yes | 11/1.88 | 10/1.89 | 6/1.90 | 9/4.75 | 16/3.85 | 10/4.37 | 37/17.86 |
| PnP+RANSAC + GT K | yes | 12/1.91 | 11/1.67 | 6/2.04 | 10/4.68 | 15/3.71 | 10/4.21 | 37/17.39 |
| PnPf+RANSAC | no | 6/1.66 | 5/1.67 | 3/2.01 | 11/4.84 | 10/3.75 | 9/3.96 | 50/17.35 |
| DeepBA | no | 3/1.66 | 3/1.67 | 2/1.66 | 8/4.80 | 8/3.86 | 6/4.30 | 30/18.30 |
@article{chui2026deepba,
  title   = {Deep Bundle Adjustment},
  author  = {Chui, Pak Hong and Andrade-Loarca, Hector and Cremers, Daniel},
  journal = {arXiv preprint arXiv:2611.18256},
  year    = {2026},
  eprint  = {2611.18256},
  archivePrefix = {arXiv},
  primaryClass  = {cs.CV}
}